ClovisLLM - GLM 5.3

ClovisLLM will soon move to GLM 5.3, replacing GLM 5.2. Discover the improvements in this new version through a performance comparison of both models and leading alternatives on the market.
The ClovisLLM migration to GLM 5.3 will take place on 2 November 2026.
GLM 5.3 retains GLM 5.2’s base model; its gains come from post-training, according to Z.ai’s official model card.
Key figures
Both columns below come from the same table published by Z.ai for GLM 5.3. All bars share a scale from 0 to 100.
Source: GLM 5.3 official model card — benchmarks and protocols. These results are published by the model developer and were not measured on Clovis.
Comparison with other market models
This chart compares GLM 5.3 and GLM 5.2 with Kimi K3, Fable 5, and GPT-5.6 Sol across six benchmarks.
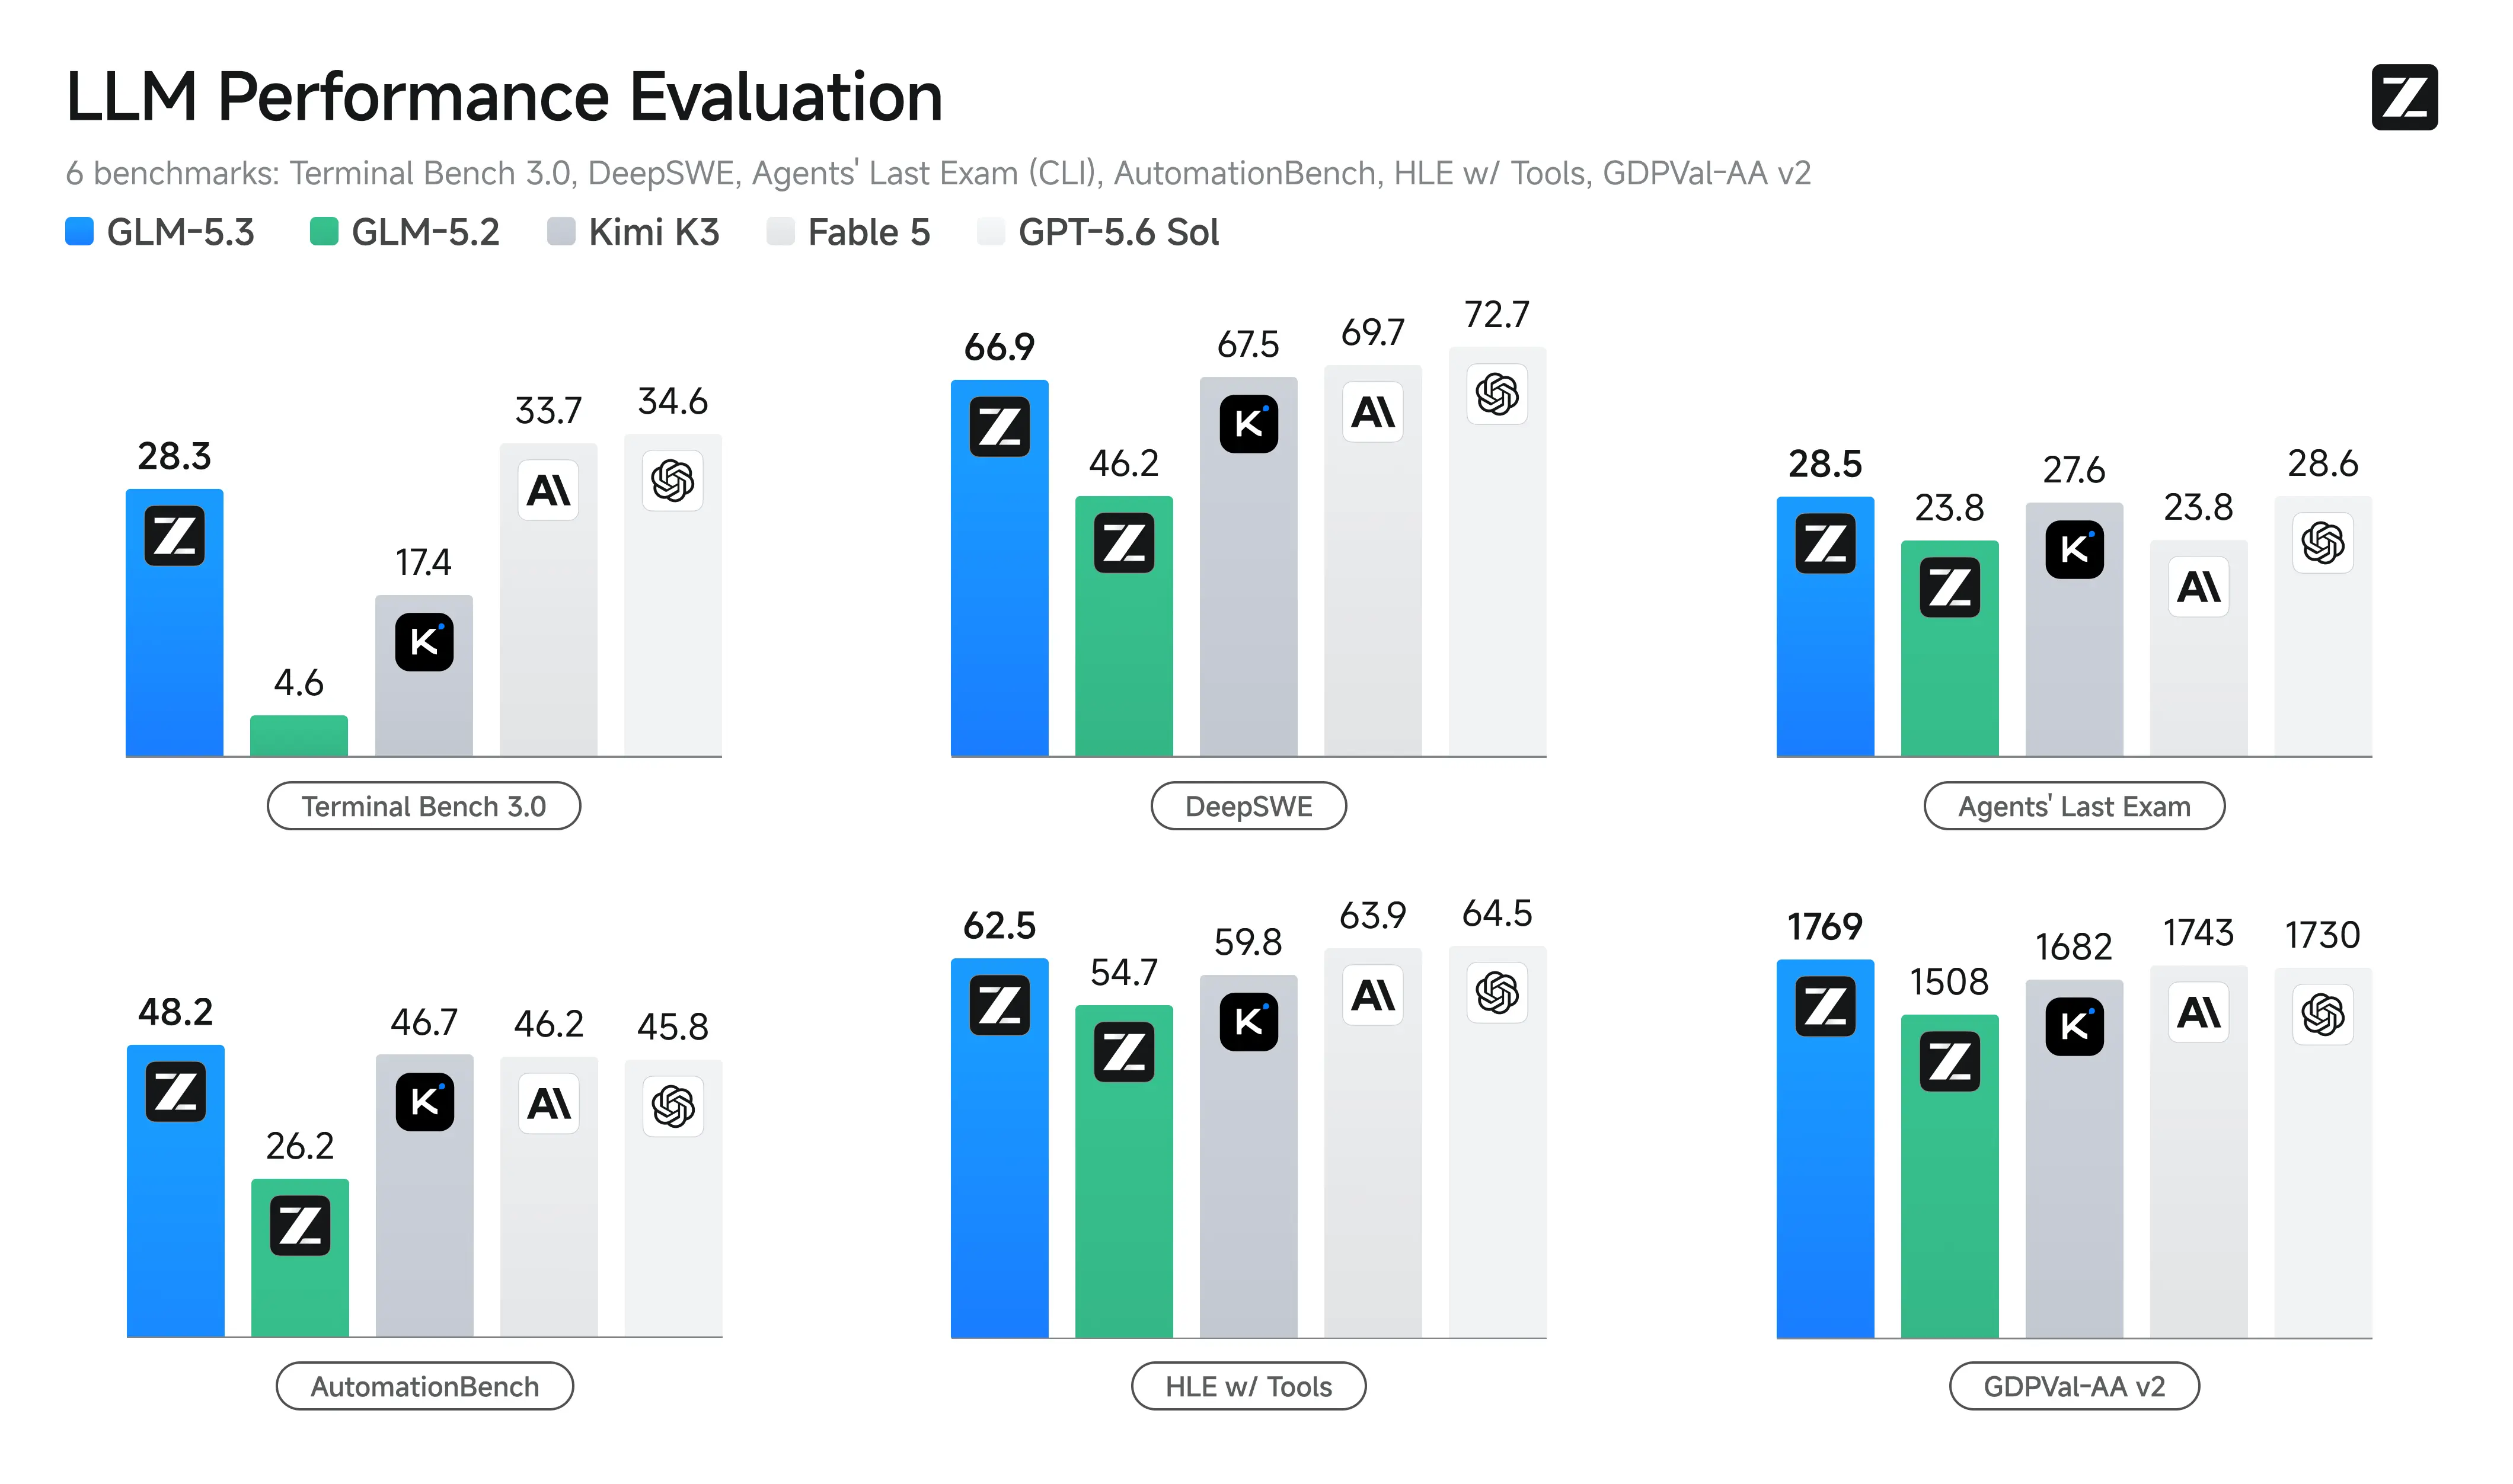
Source: Z.ai’s official GLM 5.3 comparison.
A stronger model for software engineering and agents
With GLM 5.3, improvements mainly concern tasks that require sustained work on a project. DeepSWE rises from 46.2 to 66.9, and SWE-Marathon from 19.4 to 42.5. These results suggest a better ability to complete a software change: understand the existing code, modify the relevant files, run tests, and fix the errors encountered.
The other improvement concerns agents that use tools. With 73.0 on Toolathlon Verified and 48.2 on AutomationBench, GLM 5.3 improves on tasks that combine several actions. For ClovisLLM, the expected benefit is better support for workflows where the model needs to retrieve information, act on it, and continue working with the results.